Ensemble Modeling for Accumulator Construction: Blending Soccer Analytics, Racing Handicaps, and Tennis Metrics
David Patterson · Oct 19, 2026
Ensemble Modeling for Accumulator Construction: Blending Soccer Analytics, Racing Handicaps, and Tennis Metrics
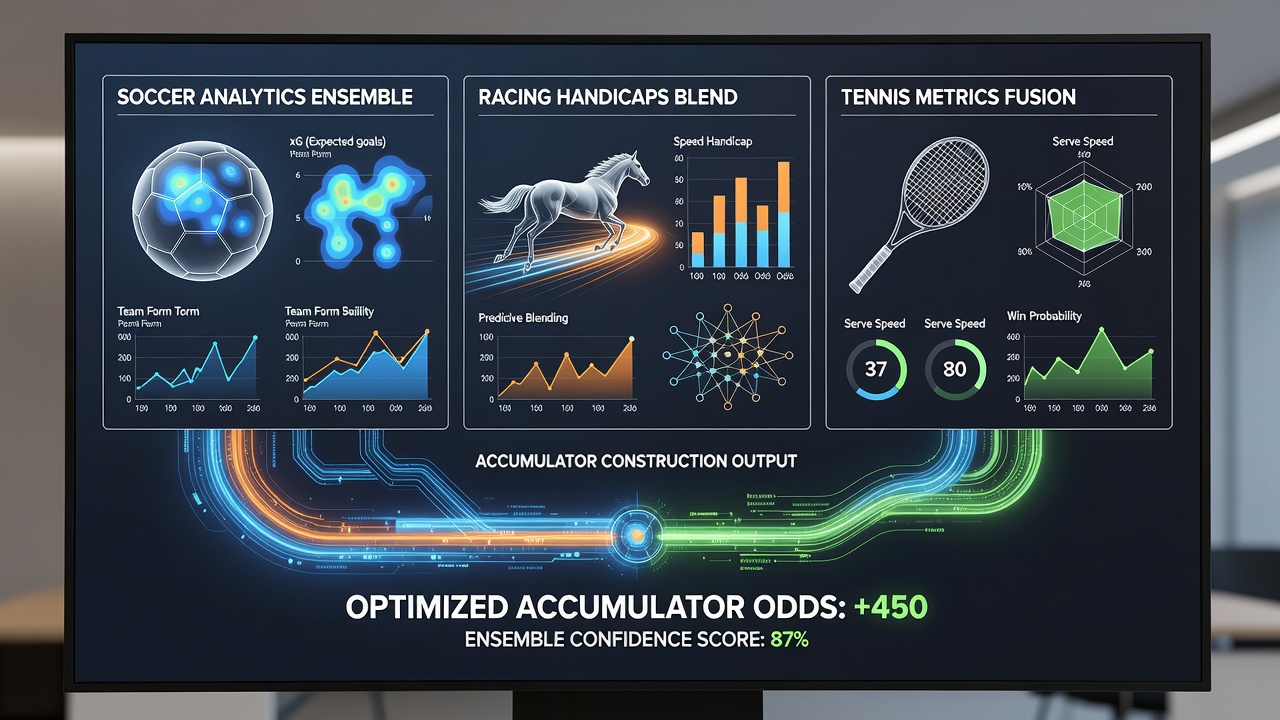
Ensemble modeling combines multiple predictive algorithms to generate more robust outputs than any single model can achieve on its own, and this approach has gained traction among analysts constructing accumulators across soccer, horse racing and tennis. Data scientists apply techniques such as random forests, gradient boosting and stacked regressions to merge disparate datasets, which allows the resulting probability estimates to account for both sport-specific patterns and cross-sport correlations that influence multi-leg bets.
Core Components of Soccer Analytics in Ensemble Frameworks
Soccer datasets typically feed expected goals models, possession-adjusted passing networks and set-piece efficiency ratings into the ensemble pipeline, while researchers integrate these variables with player tracking coordinates recorded at 25 frames per second. Studies published by the Canadian Sport Institute demonstrate that blending these metrics with historical weather and travel data improves accuracy for matches scheduled in October 2026 across major European leagues. Analysts then normalize the outputs so they align with the probability scales used for racing and tennis legs, creating a unified input layer that feeds the meta-learner.
Racing Handicaps and Their Role in Multi-Sport Stacking
Handicappers in thoroughbred racing rely on speed figures, sectional times and class ratings that get recalculated after every meeting, and these numbers enter ensemble systems through weighted regression layers that adjust for track bias and pace scenarios. Observers note that combining racing data with soccer-derived rest and travel metrics produces sharper estimates for weekend accumulators that span both codes, because fatigue patterns observed in one sport often mirror those seen in the other. Australian researchers at the Racing Science Centre have documented how ensemble outputs reduce variance in longshot selections when models incorporate both turf condition variables and international form lines updated through the 2026 spring carnival.
Tennis Metrics and Cross-Sport Calibration
Tennis analytics supply serve percentages, return point win rates and surface-specific rally lengths that ensemble builders convert into expected game-win probabilities before stacking them with soccer and racing forecasts. Because tennis matches feature fewer variables than team sports, the models apply heavier regularization to prevent overfitting when these clean inputs mix with noisier football or racing data streams. In October 2026, several ATP and WTA events coincide with major racing festivals, which gives analysts fresh opportunities to test whether surface transition effects in tennis correlate with similar performance drops observed in horses moving between all-weather and turf.
Construction of Accumulator Probability Chains
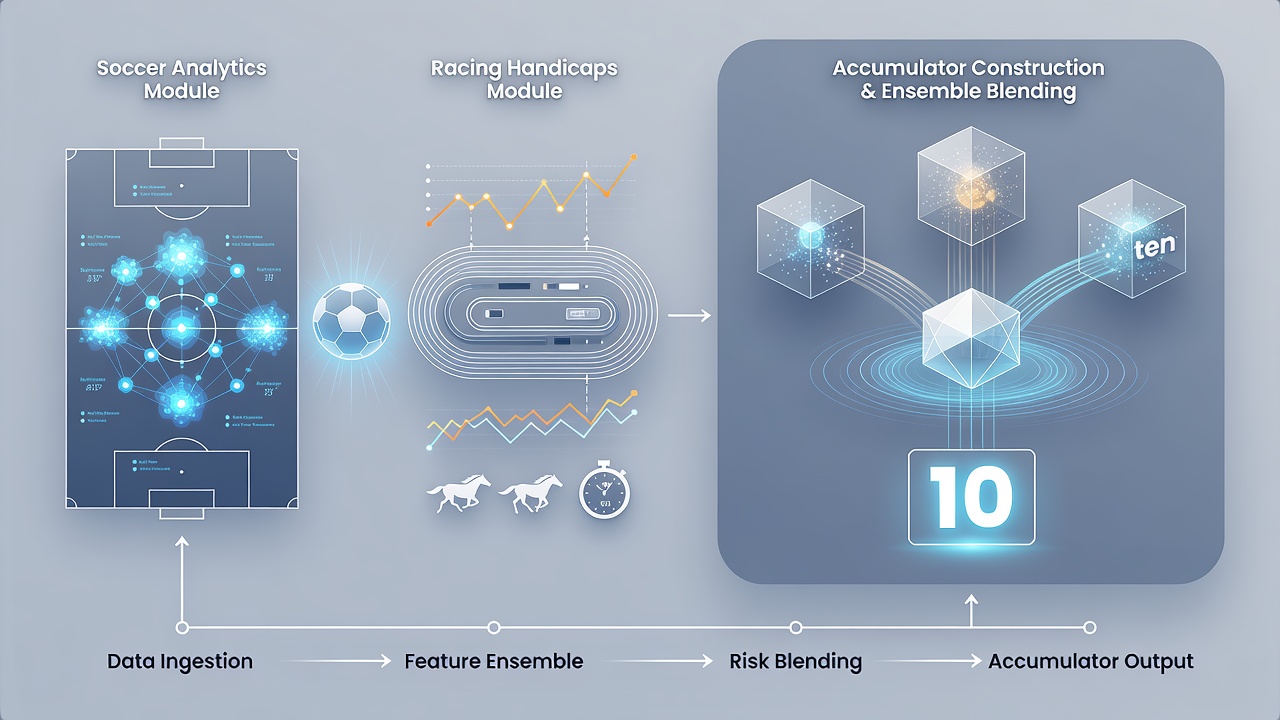
Once individual sport models generate their probability vectors, the ensemble meta-learner applies techniques such as Bayesian model averaging or neural network stacking to produce a single joint probability for the entire accumulator. This step accounts for dependence between legs, since a long layoff in racing may share latent factors wth fixture congestion in soccer squads. Practitioners calibrate the final outputs against historical payout distributions so that the model does not systematically overstate or understate combined odds, and they refresh weights weekly using the most recent results from all three sports.
Data Integration Challenges and Solutions
Different sampling frequencies across sports create alignment issues that ensemble pipelines address through interpolation and time-series alignment algorithms. Soccer event data arrives in near real time, racing results appear in discrete blocks after each race, and tennis point-by-point logs update continuously during matches, yet researchers have developed synchronization layers that allow the models to ingest these streams without introducing temporal bias. Validation sets drawn from the 2025-2026 seasons show that properly aligned ensembles maintain calibration across accumulator lengths ranging from three to seven legs.
Practical Deployment in October 2026
With the Premier League, Breeders' Cup preliminaries and several indoor tennis tournaments running concurrently in October 2026, operators have begun publishing accumulator products whose odds derive directly from ensemble outputs. These products incorporate live model updates that adjust probabilities after each completed leg, allowing bettors to see revised prices for remaining selections. Regulatory filings from the Australian Competition and Consumer Commission indicate that such dynamic pricing requires transparent disclosure of the underlying data sources to maintain compliance standards.
Conclusion
Ensemble modeling supplies a structured method for merging soccer analytics, racing handicaps and tennis metrics into coherent accumulator forecasts, and ongoing refinements continue to improve calibration as new data arrives each season. The approach relies on careful feature engineering, cross-sport normalization and regular validation against actual outcomes rather than any single sport's internal logic. As competitions unfold through late 2026, the same frameworks that processed earlier cycles remain available for analysts seeking consistent probability estimates across the three codes.